Systematic review search strategy and de-duplicationกลยุทธ์การสืบค้นและการคัดรายการซ้ำสำหรับการทบทวนวรรณกรรมอย่างเป็นระบบ
Systematic review: search strategy and de-duplicationการทบทวนวรรณกรรมอย่างเป็นระบบ: กลยุทธ์การสืบค้นและการคัดรายการซ้ำออก
An invented review question in workplace health, written as PICO: among adults whose work is mainly desk-based, do workplace programmes that break up sitting, compared with usual working arrangements, change sitting time at work? The question is invented and every record is simulated: the 1,400 bibliographic records, with their titles, authors, journal names and DOI-like identifiers, were generated by code with a fixed seed, so no real study, real database search or client project is involved.คำถามการทบทวนวรรณกรรมที่สมมุติขึ้นในหัวข้อสุขภาพในที่ทำงาน เขียนในรูปแบบ PICO: ในผู้ใหญ่ที่ทำงานนั่งโต๊ะเป็นหลัก โปรแกรมในที่ทำงานที่ช่วยลดการนั่งต่อเนื่อง เมื่อเทียบกับรูปแบบการทำงานตามปกติ ทำให้เวลานั่งระหว่างทำงานเปลี่ยนไปหรือไม่ คำถามนี้สมมุติขึ้น และทุกรายการเป็นข้อมูลจำลอง รายการบรรณานุกรมทั้ง 1,400 รายการ รวมทั้งชื่อเรื่อง ชื่อผู้แต่ง ชื่อวารสาร และรหัสที่มีรูปแบบคล้าย DOI สร้างขึ้นด้วยโค้ดโดยกำหนด seed คงที่ จึงไม่เกี่ยวข้องกับงานวิจัยจริง การสืบค้นฐานข้อมูลจริง หรืองานของลูกค้ารายใด
What you receiveสิ่งที่คุณจะได้รับ
A search strategy for each database, built from your review question, and de-duplication of the records found, with the count at every step.สร้างกลยุทธ์การสืบค้นสำหรับแต่ละฐานข้อมูลจากคำถามการทบทวนของคุณ และคัดรายการซ้ำออกจากผลการสืบค้น พร้อมแสดงจำนวนในทุกขั้นตอน
- A search strategy for each database, line by line, with the number of records each line finds.กลยุทธ์การสืบค้นรายฐานข้อมูล แสดงทีละบรรทัดพร้อมจำนวนรายการที่แต่ละบรรทัดค้นพบ
- The record count before and after each de-duplication step.จำนวนรายการก่อนและหลังการคัดรายการซ้ำในแต่ละขั้น
- A flow diagram of the identification stage.แผนภาพแสดงขั้นตอนการค้นหารายการ (identification)
- The de-duplicated record file, ready for your team's screening.ไฟล์รายการที่คัดรายการซ้ำแล้ว พร้อมให้ทีมของคุณคัดกรองต่อ
The sampleตัวอย่างงาน
Sample work on simulated data. No real patient, no client project.ตัวอย่างงานจากข้อมูลจำลองทั้งหมด ไม่ใช่ข้อมูลผู้ป่วยจริง และไม่ใช่งานของลูกค้ารายใด
The review questionคำถามการทบทวน
- Population (P): adults whose work is mainly desk-based.ประชากร (P): ผู้ใหญ่ที่ทำงานนั่งโต๊ะเป็นหลัก
- Intervention (I): workplace programmes that break up sitting, such as sit-stand desks, standing prompts, walking meetings or activity challenges.สิ่งแทรกแซง (I): โปรแกรมในที่ทำงานที่ช่วยลดการนั่งต่อเนื่อง เช่น โต๊ะที่ปรับระดับให้นั่งหรือยืนทำงานได้ การเตือนให้ลุกยืน การประชุมแบบเดินไปคุยไป หรือกิจกรรมท้าทายให้ขยับร่างกาย
- Comparison (C): usual working arrangements.ตัวเปรียบเทียบ (C): รูปแบบการทำงานตามปกติ
- Outcome (O): sitting time at work, measured by a wearable device or by self-report.ผลลัพธ์ (O): เวลานั่งระหว่างทำงาน วัดด้วยอุปกรณ์สวมใส่หรือจากการรายงานของผู้เข้าร่วมเอง
What a job like this deliversสิ่งที่ส่งมอบในงานลักษณะนี้
- The search strategy for each database, line by line in that database's own syntax, ready to rerun and to report in an appendix.กลยุทธ์การสืบค้นของแต่ละฐานข้อมูลทีละบรรทัด เขียนตามไวยากรณ์ของฐานข้อมูลนั้น พร้อมนำไปสืบค้นซ้ำและรายงานในภาคผนวก
- The de-duplicated record set, in which every removed record names the record kept in its place, and a list of the pairs that need a human decision.ชุดรายการที่คัดรายการซ้ำออกแล้ว ซึ่งทุกรายการที่ถูกตัดออกระบุว่ารายการใดถูกเก็บไว้แทน พร้อมรายชื่อคู่ที่ต้องให้คนตัดสิน
- The counts at each step, a short methods note and a flow diagram from identification to the records that go to screening.จำนวนรายการในแต่ละขั้น บันทึกวิธีการฉบับย่อ และแผนภาพการไหลของรายการตั้งแต่การสืบค้นจนถึงรายการที่ส่งต่อไปคัดกรอง
Search strategyกลยุทธ์การสืบค้น
Each block below is the strategy for one database, with its lines numbered in the order they are run. The sitting concept and the workplace concept are each searched with subject headings, where the database has them, and with free-text words in the title and abstract. A line that joins earlier lines by their numbers is a Boolean combination line: OR widens one concept and AND joins the two concepts. The last line of each block is the set exported for de-duplication. The 2015-2024 publication-year limit on that line is part of the invented review scope; a real strategy states the reason for any date limit.แต่ละบล็อกด้านล่างคือกลยุทธ์การสืบค้นของฐานข้อมูลหนึ่งแห่ง บรรทัดเรียงหมายเลขตามลำดับที่สืบค้น แนวคิดเรื่องการนั่งและแนวคิดเรื่องที่ทำงานสืบค้นทั้งด้วยหัวเรื่องมาตรฐาน (หากฐานข้อมูลนั้นมี) และด้วยคำอิสระในชื่อเรื่องและบทคัดย่อ บรรทัดที่นำหมายเลขบรรทัดก่อนหน้ามารวมกันคือบรรทัดรวมแบบบูลีน โดย OR ใช้ขยายขอบเขตของแนวคิดเดียวกัน และ AND ใช้เชื่อมสองแนวคิดเข้าด้วยกัน บรรทัดสุดท้ายของแต่ละบล็อกคือชุดรายการที่ส่งออกไปคัดรายการซ้ำ การจำกัดปีที่ตีพิมพ์ 2015-2024 ในบรรทัดนั้นเป็นส่วนหนึ่งของขอบเขตการทบทวนที่สมมุติขึ้น กลยุทธ์จริงต้องระบุเหตุผลของการจำกัดช่วงปีทุกครั้ง
The record counts in these search blocks are synthetic. They come from the simulated record set made for this page, not from real database hits, and show only how a delivered strategy reports its counts line by line. The last line of each block equals the records that source contributes to the de-duplication table.จำนวนรายการในบล็อกการสืบค้นเหล่านี้เป็นตัวเลขสังเคราะห์ ได้จากชุดรายการจำลองที่สร้างขึ้นสำหรับหน้านี้ ไม่ใช่จำนวนที่พบจริงในฐานข้อมูล และมีไว้เพื่อแสดงรูปแบบการรายงานจำนวนทีละบรรทัดในกลยุทธ์ที่ส่งมอบเท่านั้น บรรทัดสุดท้ายของแต่ละบล็อกเท่ากับจำนวนรายการของแหล่งนั้นในตารางการคัดรายการซ้ำ
Source A · biomedical index with subject headingsSubject headings (a heading followed by /), free-text words with the .ti,ab. field tag, the adj proximity operator and Boolean combination lines. Record counts are synthetic, from the simulated record set, not real database hits.หัวเรื่องมาตรฐาน (หัวเรื่องที่ตามด้วย /) คำอิสระที่ระบุเขตข้อมูล .ti,ab. ตัวดำเนินการ adj สำหรับคำที่อยู่ใกล้กัน และบรรทัดรวมแบบบูลีน จำนวนรายการเป็นตัวเลขสังเคราะห์จากชุดรายการจำลอง ไม่ใช่จำนวนที่พบจริงในฐานข้อมูล
- #1Sedentary Behavior/1,299 recordsรายการ
- #2Sitting Position/714 recordsรายการ
- #3(sedentar* or sitting or seated or sit-stand or "sit stand").ti,ab.3,355 recordsรายการ
- #4((prolonged or uninterrupted or break*) adj3 (sit* or seated)).ti,ab.439 recordsรายการ
- #5or/1-43,638 recordsรายการ
- #6Workplace/6,202 recordsรายการ
- #7Occupational Health/5,169 recordsรายการ
- #8(workplace* or worksite* or office* or employee* or desk-based or "desk based").ti,ab.18,937 recordsรายการ
- #9or/6-820,930 recordsรายการ
- #105 and 9753 recordsรายการ
- #11limit 10 to yr="2015 - 2024"527 recordsรายการ
Source B · biomedical index with an exploded thesaurusThesaurus terms exploded with /exp, free-text words with the :ti,ab,kw field codes, the NEAR/n proximity operator and Boolean combination lines. Record counts are synthetic, from the simulated record set, not real database hits.คำศัพท์ในอรรถาภิธานที่ขยายรวมคำย่อยด้วย /exp คำอิสระที่ระบุเขตข้อมูล :ti,ab,kw ตัวดำเนินการ NEAR/n สำหรับคำที่อยู่ใกล้กัน และบรรทัดรวมแบบบูลีน จำนวนรายการเป็นตัวเลขสังเคราะห์จากชุดรายการจำลอง ไม่ใช่จำนวนที่พบจริงในฐานข้อมูล
- #1'sedentary lifestyle'/exp1,386 recordsรายการ
- #2'sitting'/exp995 recordsรายการ
- #3sedentar*:ti,ab,kw OR sitting:ti,ab,kw OR seated:ti,ab,kw OR 'sit stand':ti,ab,kw3,077 recordsรายการ
- #4((prolonged OR uninterrupted OR break*) NEAR/3 (sit* OR seated)):ti,ab,kw404 recordsรายการ
- #5#1 OR #2 OR #3 OR #43,402 recordsรายการ
- #6'workplace'/exp6,682 recordsรายการ
- #7'occupational health'/exp5,751 recordsรายการ
- #8workplace*:ti,ab,kw OR worksite*:ti,ab,kw OR office*:ti,ab,kw OR employee*:ti,ab,kw OR 'desk based':ti,ab,kw17,115 recordsรายการ
- #9#6 OR #7 OR #819,184 recordsรายการ
- #10#5 AND #9688 recordsรายการ
- #11#10 AND [2015-2024]/py487 recordsรายการ
Source C · multidisciplinary citation indexTopic searches with TS= (title, abstract and keywords), the NEAR/n proximity operator and Boolean combination lines; this index has no subject-heading thesaurus, so both concepts are searched as free text. Record counts are synthetic, from the simulated record set, not real database hits.การสืบค้นตามหัวข้อด้วย TS= (ชื่อเรื่อง บทคัดย่อ และคำสำคัญ) ตัวดำเนินการ NEAR/n และบรรทัดรวมแบบบูลีน ดัชนีนี้ไม่มีอรรถาภิธานหัวเรื่องมาตรฐาน จึงสืบค้นทั้งสองแนวคิดด้วยคำอิสระ จำนวนรายการเป็นตัวเลขสังเคราะห์จากชุดรายการจำลอง ไม่ใช่จำนวนที่พบจริงในฐานข้อมูล
- #1TS=(sedentar* OR sitting OR seated OR "sit-stand" OR "sit stand")2,743 recordsรายการ
- #2TS=((prolonged OR uninterrupted OR break*) NEAR/3 (sit* OR seated))312 recordsรายการ
- #3#1 OR #22,757 recordsรายการ
- #4TS=(workplace* OR worksite* OR office* OR employee* OR "desk-based" OR "desk based")15,040 recordsรายการ
- #5#3 AND #4555 recordsรายการ
- #6#5 AND PY=(2015-2024)386 recordsรายการ
De-duplicationการคัดรายการซ้ำออก
Methods note. The records exported from the three sources were pooled and de-duplicated in three steps, each run on the records left by the step before. The first step matches exact identifiers: records with the same DOI, ignoring letter case. The second step matches the normalised title, written in lower case with punctuation and extra spaces removed, together with the publication year.บันทึกวิธีการ รายการที่ส่งออกจากทั้งสามแหล่งถูกนำมารวมกันแล้วคัดรายการซ้ำออกสามขั้น แต่ละขั้นทำกับรายการที่เหลือจากขั้นก่อนหน้า ขั้นแรกจับคู่ด้วยรหัสระบุรายการที่ตรงกัน คือรายการที่มี DOI เดียวกันเมื่อไม่นับความต่างของตัวพิมพ์เล็กและตัวพิมพ์ใหญ่ ขั้นที่สองจับคู่ด้วยชื่อเรื่องที่ปรับให้อยู่ในรูปมาตรฐาน คือเปลี่ยนเป็นตัวพิมพ์เล็กและตัดเครื่องหมายวรรคตอนกับช่องว่างส่วนเกินออก ร่วมกับปีที่ตีพิมพ์
The third step matches titles by similarity, with an author check. The normalised titles are compared over the length of the shorter title, so a title with and without its subtitle can still match. A pair matches when the similarity, 1 - d/L (d = edit distance between the shorter title and the same number of opening characters of the longer title; L = length of the shorter title), is at least 0.90, the publication years are at most 1 year apart, and the first author has the same surname and first initial, so a record that drops a middle initial still matches.ขั้นที่สามจับคู่ด้วยความคล้ายคลึงของชื่อเรื่องร่วมกับการตรวจชื่อผู้แต่ง โดยเทียบชื่อเรื่องที่ปรับให้อยู่ในรูปมาตรฐานแล้วตลอดความยาวของชื่อเรื่องที่สั้นกว่า ชื่อเรื่องที่มีและไม่มีชื่อเรื่องรองจึงยังจับคู่กันได้ คู่รายการจะถือว่าตรงกันเมื่อค่าความคล้ายคลึง 1 - d/L (d คือระยะการแก้ไขหรือ edit distance ระหว่างชื่อเรื่องที่สั้นกว่ากับอักษรช่วงต้นของชื่อเรื่องที่ยาวกว่าในจำนวนเท่ากัน และ L คือความยาวของชื่อเรื่องที่สั้นกว่า) ไม่ต่ำกว่า 0.90 ปีที่ตีพิมพ์ต่างกันไม่เกิน 1 ปี และผู้แต่งคนแรกมีนามสกุลและอักษรย่อของชื่อต้นเหมือนกัน รายการที่ไม่มีอักษรย่อของชื่อกลางจึงยังจับคู่ได้
In each group of duplicates one record is kept: the one with a DOI, then the one with the longer title, then the one from the earlier source in the order A, B, C. Two records with different DOIs are never merged, and a conference abstract is never merged with a full paper: such a pair is flagged for a human decision and both records stay in the set.ในแต่ละกลุ่มของรายการซ้ำจะเก็บไว้หนึ่งรายการ โดยเลือกรายการที่มี DOI ก่อน ตามด้วยรายการที่ชื่อเรื่องยาวกว่า แล้วจึงเป็นรายการจากแหล่งที่มาก่อนตามลำดับ A, B, C สองรายการที่มี DOI ต่างกันจะไม่ถูกรวมกันเลย และบทคัดย่อจากการประชุมวิชาการจะไม่ถูกรวมกับบทความฉบับเต็ม คู่ลักษณะนี้จะถูกระบุไว้ให้ผู้ทบทวนตัดสิน และเก็บไว้ทั้งสองรายการ
| Source or step | Records | Removed | Injected* | Difference | Flagged pairs† |
|---|---|---|---|---|---|
| Records identified | |||||
| Source A, biomedical index with subject headings | 527 | ||||
| Source B, biomedical index with an exploded thesaurus | 487 | ||||
| Source C, multidisciplinary citation index | 386 | ||||
| All sources | 1,400 | ||||
| De-duplication steps, run in order | |||||
| 1. Exact DOI match | 1,170 | 230 | 230 | 0 | 0 |
| 2. Normalised title and year | 1,122 | 48 | 48 | 0 | 0 |
| 3. Title similarity and first author | 1,064 | 58 | 58 | 0 | 24 |
| Result | |||||
| Total removed | 336 | 336 | 0 | ||
| Records to screen | 1,064 | 24 | |||
- * Injected: duplicates planted in the simulated set by code, counted by the kind each step targets: 230 copies with the same DOI (first step); 48 copies with another letter case and punctuation and no DOI (second step); 32 copies without the subtitle and 26 copies with first initials only and the print year, 1 year after the online year, 6 of them also with US spelling in the title (third step).* Injected: รายการซ้ำที่ใช้โค้ดฝังไว้ในชุดข้อมูลจำลอง นับตามชนิดที่แต่ละขั้นมุ่งตรวจหา ได้แก่ สำเนาที่มี DOI เดียวกัน 230 รายการ (ขั้นแรก) สำเนาที่ต่างกันเฉพาะตัวพิมพ์เล็กใหญ่กับเครื่องหมายวรรคตอนและไม่มี DOI 48 รายการ (ขั้นที่สอง) สำเนาที่ไม่มีชื่อเรื่องรอง 32 รายการ และสำเนาที่ผู้แต่งมีเฉพาะอักษรย่อของชื่อต้นและใช้ปีของฉบับพิมพ์ ซึ่งช้ากว่าปีของฉบับออนไลน์ 1 ปี 26 รายการ โดย 6 รายการในจำนวนนี้สะกดชื่อเรื่องแบบอเมริกันด้วย (ขั้นที่สาม)
- † Flagged pairs: 24 conference abstracts were planted, each 1 year before its full paper. An abstract and its full paper are two reports, not duplicates, so both stay in the set and the review team decides.† Flagged pairs: ฝังบทคัดย่อจากการประชุมวิชาการไว้ 24 รายการ แต่ละรายการเผยแพร่ก่อนบทความฉบับเต็มของงานเดียวกัน 1 ปี บทคัดย่อกับบทความฉบับเต็มเป็นรายงานสองชิ้น ไม่ใช่รายการซ้ำ จึงเก็บไว้ทั้งคู่ให้ทีมผู้ทบทวนตัดสิน
- Records: records exported by a source, or left after a step. Difference: removed minus injected.Records: จำนวนรายการที่แหล่งข้อมูลส่งออก หรือที่เหลือหลังแต่ละขั้น Difference: จำนวนที่ตัดออกลบด้วยจำนวนที่ฝังไว้
How to read the table. The first rows give the records exported from each source. Each step row gives the records left after that step and the records it removed. Because the records are simulated, the planted duplicates are known: the Injected column gives how many duplicates of the kind each step targets were planted, and the Difference column (removed minus injected) is 0 at every step, so each step removed as many records as were planted for it. A count alone cannot show that the right records were merged, because one wrong merge and one missed duplicate cancel out; a record-by-record check against the simulation truth also confirms that each of the 1,040 simulated papers keeps exactly one full-paper record and that every flagged pair is an abstract with its own full paper. In all, 336 of 1,400 records (24.0%) were removed and 1,064 go to screening. A real job has no Injected column; there, a random sample of each step's matches is read by a person instead.วิธีอ่านตาราง แถวแรก ๆ แสดงจำนวนรายการที่ส่งออกจากแต่ละแหล่ง แถวของแต่ละขั้นแสดงจำนวนรายการที่เหลือหลังขั้นนั้นและจำนวนที่ถูกตัดออก เนื่องจากรายการทั้งหมดเป็นข้อมูลจำลอง จึงรู้ล่วงหน้าว่าฝังรายการซ้ำไว้เท่าใด คอลัมน์ Injected แสดงจำนวนรายการซ้ำชนิดที่แต่ละขั้นมุ่งตรวจหาซึ่งฝังไว้ และคอลัมน์ Difference (จำนวนที่ตัดออกลบด้วยจำนวนที่ฝังไว้) เท่ากับ 0 ทุกขั้น แสดงว่าแต่ละขั้นตัดรายการออกเท่ากับจำนวนที่ฝังไว้สำหรับขั้นนั้น แต่จำนวนนับอย่างเดียวยืนยันไม่ได้ว่ารวมรายการถูกคู่ เพราะการรวมผิดหนึ่งครั้งกับการพลาดรายการซ้ำหนึ่งครั้งหักลบกันได้ จึงตรวจทีละรายการเทียบกับคำตอบของการจำลองด้วย และการตรวจนี้ยืนยันว่าบทความจำลองทั้ง 1,040 เรื่องเหลือบทความฉบับเต็มเรื่องละหนึ่งรายการพอดี และทุกคู่ที่ระบุไว้คือบทคัดย่อกับบทความฉบับเต็มของงานเดียวกัน โดยรวมตัดรายการออก 336 จาก 1,400 รายการ (24.0%) และเหลือ 1,064 รายการที่ส่งต่อไปคัดกรอง ในงานจริงไม่มีคอลัมน์ Injected จึงสุ่มคู่ที่จับได้ในแต่ละขั้นมาให้ผู้ตรวจอ่านยืนยันแทน
Flow of recordsแผนภาพการไหลของรายการ
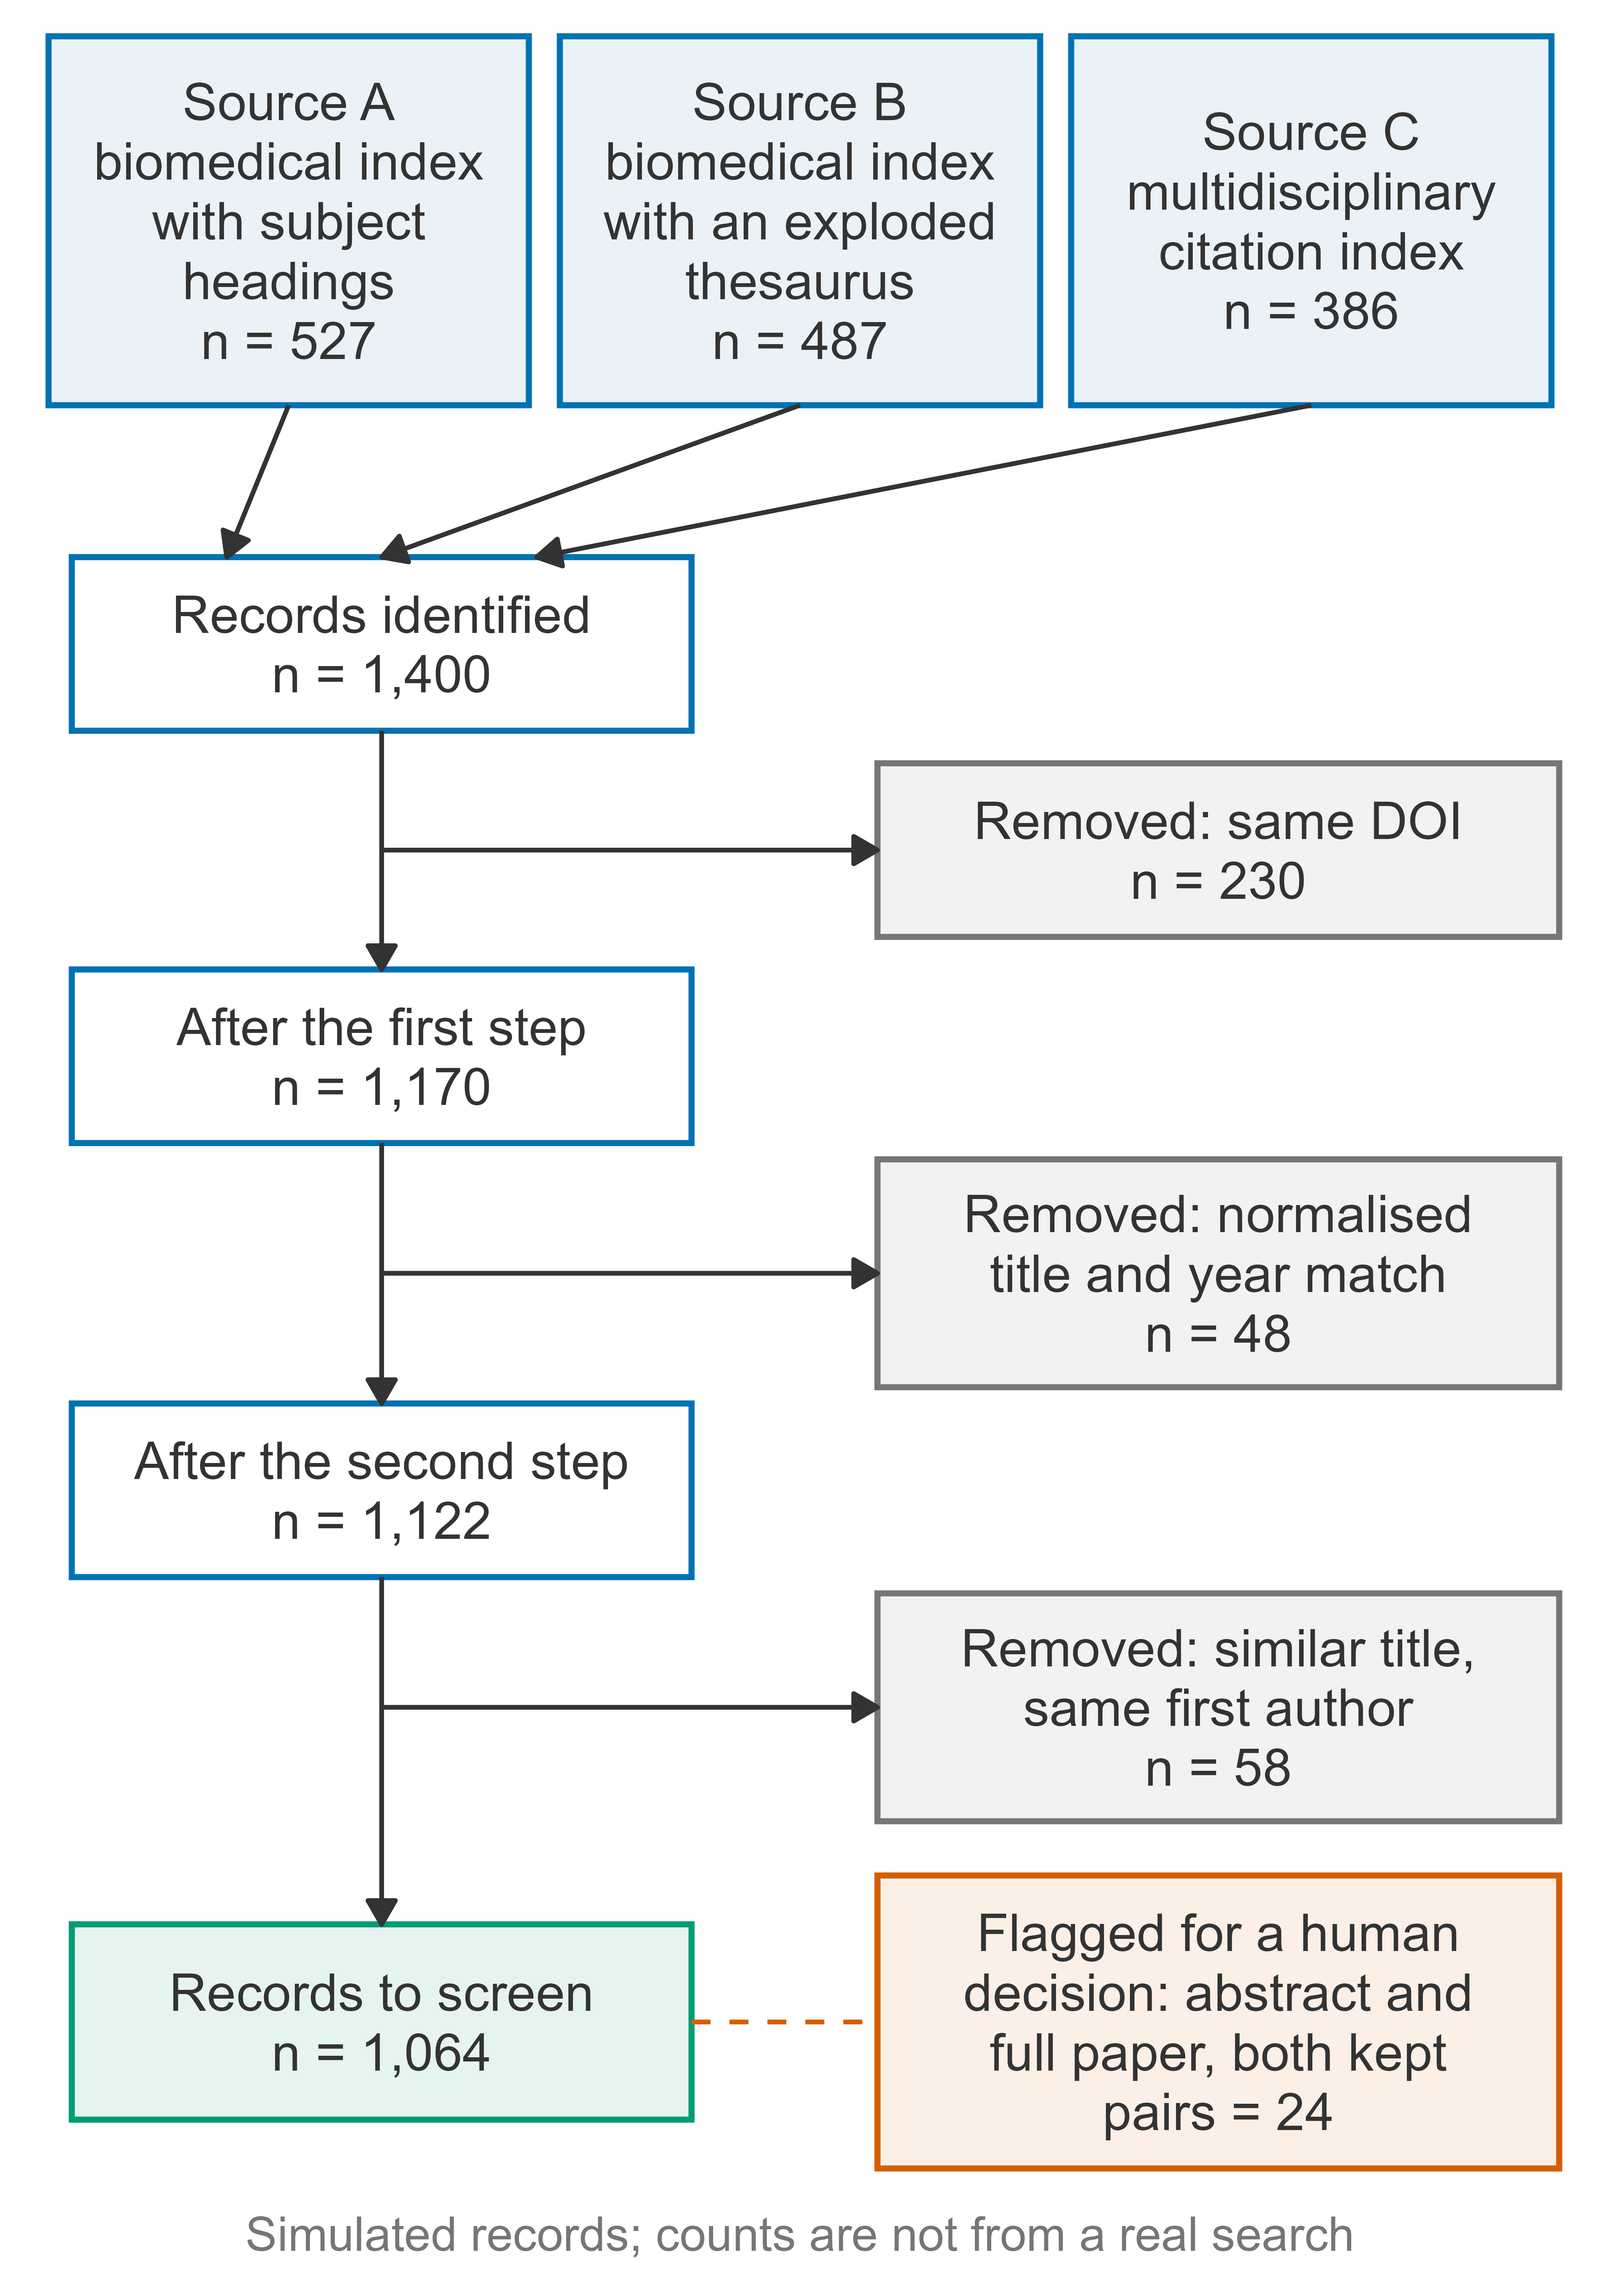
How to read the diagram. Read it from top to bottom. The three source boxes feed the records identified; each box on the left gives the records still in the set, and each box on the right gives the records taken out at that step and why. The dashed line leads to the 24 pairs flagged for a human decision; both records of each pair are counted among the records to screen. The diagram is the identification part of a standard review flow diagram; the review team adds screening and inclusion.วิธีอ่านแผนภาพ อ่านจากบนลงล่าง กล่องของแหล่งข้อมูลทั้งสามแหล่งชี้เข้าสู่กล่องรายการที่สืบค้นพบ กล่องด้านซ้ายแต่ละกล่องแสดงจำนวนรายการที่ยังอยู่ในชุด และกล่องด้านขวาแสดงจำนวนรายการที่ถูกตัดออกในขั้นนั้นพร้อมเหตุผล เส้นประชี้ไปยังคู่ที่ระบุไว้ให้ผู้ทบทวนตัดสิน 24 คู่ ซึ่งทั้งสองรายการของแต่ละคู่ยังนับรวมอยู่ในรายการที่ส่งไปคัดกรอง แผนภาพนี้คือส่วนการสืบค้น (identification) ของแผนภาพการไหลมาตรฐานของการทบทวนวรรณกรรมอย่างเป็นระบบ ทีมผู้ทบทวนจะเพิ่มส่วนการคัดกรองและการคัดเข้าเอง
Limits of this searchข้อจำกัดของการสืบค้นนี้
- The service delivers the search strategy, the de-duplicated record set and the counts. Screening decisions, including the decision on each flagged pair, belong to the review team.งานบริการนี้ส่งมอบกลยุทธ์การสืบค้น ชุดรายการที่คัดรายการซ้ำออกแล้ว และจำนวนในแต่ละขั้น ส่วนการตัดสินในการคัดกรอง รวมถึงการตัดสินคู่ที่ระบุไว้แต่ละคู่ เป็นหน้าที่ของทีมผู้ทบทวน
- A real job reports the real date of each search in each database, with its real record counts. This sample has no search date because no search was run.งานจริงต้องรายงานวันที่สืบค้นจริงของแต่ละฐานข้อมูลพร้อมจำนวนรายการที่พบจริง ตัวอย่างนี้ไม่มีวันที่สืบค้นเพราะไม่ได้สืบค้นฐานข้อมูลจริง
- Automatic matching can miss duplicates whose titles differ more than the threshold allows or whose first author is written differently, and it can join two different reports that share a title and a first author. The threshold trades missed duplicates against wrong merges, so borderline pairs are best read by a person.การจับคู่อัตโนมัติอาจพลาดรายการซ้ำที่ชื่อเรื่องต่างกันเกินเกณฑ์ หรือที่เขียนชื่อผู้แต่งคนแรกต่างกัน และอาจรวมรายงานสองชิ้นที่ต่างกันแต่มีชื่อเรื่องและผู้แต่งคนแรกเหมือนกัน การเลือกเกณฑ์จึงเป็นการชั่งน้ำหนักระหว่างการพลาดรายการซ้ำกับการรวมรายการผิด คู่ที่ก้ำกึ่งจึงควรให้คนอ่านตรวจ
- The subject headings, field tags and operators follow the usual syntax of each database family. A delivered strategy is checked against the live interface of the database the review team uses, because headings and syntax change over time.หัวเรื่องมาตรฐาน ตัวระบุเขตข้อมูล และตัวดำเนินการ เขียนตามไวยากรณ์ที่ใช้กันทั่วไปของฐานข้อมูลแต่ละกลุ่ม กลยุทธ์ที่ส่งมอบจริงต้องตรวจกับหน้าจอสืบค้นปัจจุบันของฐานข้อมูลที่ทีมผู้ทบทวนใช้ เพราะหัวเรื่องและไวยากรณ์เปลี่ยนแปลงได้ตามเวลา
- No clinical conclusion is drawn here: the sample shows how records are found and de-duplicated, not what the studies found. Interpretation belongs to the buyer.ตัวอย่างนี้ไม่ได้สรุปผลทางคลินิกใด ๆ แสดงเพียงวิธีหารายการและคัดรายการซ้ำออก ไม่ได้แสดงว่างานวิจัยเหล่านั้นพบอะไร การแปลผลเป็นหน้าที่ของผู้ว่าจ้าง
What you send and do yourselfสิ่งที่คุณต้องส่งและทำเอง
- Your review question and inclusion criteria.คำถามการทบทวนและเกณฑ์การคัดเลือกการศึกษา
- The searches run under your institution's licence: you run each strategy yourself and send the exported records. Free databases such as PubMed I can search directly. I never ask for your login.สำหรับฐานข้อมูลที่สถาบันของคุณสมัครสมาชิกไว้ คุณเป็นผู้รันกลยุทธ์การสืบค้นเองแล้วส่งไฟล์รายการที่ส่งออกมาให้ ส่วนฐานข้อมูลที่เปิดให้ใช้ฟรี เช่น PubMed ผมสืบค้นให้ได้โดยตรง ผมจะไม่ขอชื่อผู้ใช้หรือรหัสผ่านของคุณ
- Your team does the screening, the data extraction and the review itself.ทีมของคุณเป็นผู้คัดกรอง สกัดข้อมูล และทำการทบทวนวรรณกรรมเอง
- You acknowledge the statistical help in the way your journal or committee asks.คุณระบุความช่วยเหลือด้านสถิติตามรูปแบบที่วารสารหรือคณะกรรมการกำหนด
Limitsขอบเขตและข้อจำกัด
- Statistical analysis and advice only: the research question, the data, the interpretation and the writing stay yours.บริการนี้เป็นงานวิเคราะห์และให้คำแนะนำทางสถิติเท่านั้น คำถามวิจัย ข้อมูล การแปลผล และการเขียน เป็นของคุณทั้งหมด
- The search covers free databases and the licensed databases you run yourself.การสืบค้นครอบคลุมฐานข้อมูลที่เปิดให้ใช้ฟรี และฐานข้อมูลที่ต้องสมัครสมาชิกซึ่งคุณเป็นผู้รันการสืบค้นเอง
- Not for a thesis, an independent study or other work submitted for a degree; for those, I offer consultation only.ไม่รับทำงานที่จะนำไปใช้เพื่อสำเร็จการศึกษา เช่น วิทยานิพนธ์ การค้นคว้าอิสระ หรือผลงานอื่นที่ยื่นเพื่อรับปริญญา งานลักษณะนี้รับเฉพาะการให้คำปรึกษา
- Authorship is not sold and is not a condition of the service.การมีชื่อเป็นผู้นิพนธ์ไม่ใช่สิ่งที่ซื้อขายได้ และไม่ใช่เงื่อนไขในการรับงาน
Request this serviceขอใช้บริการนี้
Every request is reviewed first. I may accept or decline it. The timeline is agreed per project after review.ผมพิจารณาคำขอทุกงานก่อน และอาจรับหรือปฏิเสธงาน ระยะเวลาของแต่ละงานตกลงกันหลังพิจารณาคำขอแล้ว
Member prices apply only to orders that start on uniqcret.com; if you found me on Fastwork or your enquiry began there, please order on Fastwork at the Fastwork price.ราคาสมาชิกใช้กับงานที่เริ่มต้นบน uniqcret.com เท่านั้น หากคุณรู้จักผมจาก Fastwork หรือเริ่มสอบถามบน Fastwork กรุณาสั่งงานบน Fastwork ในราคาของ Fastwork